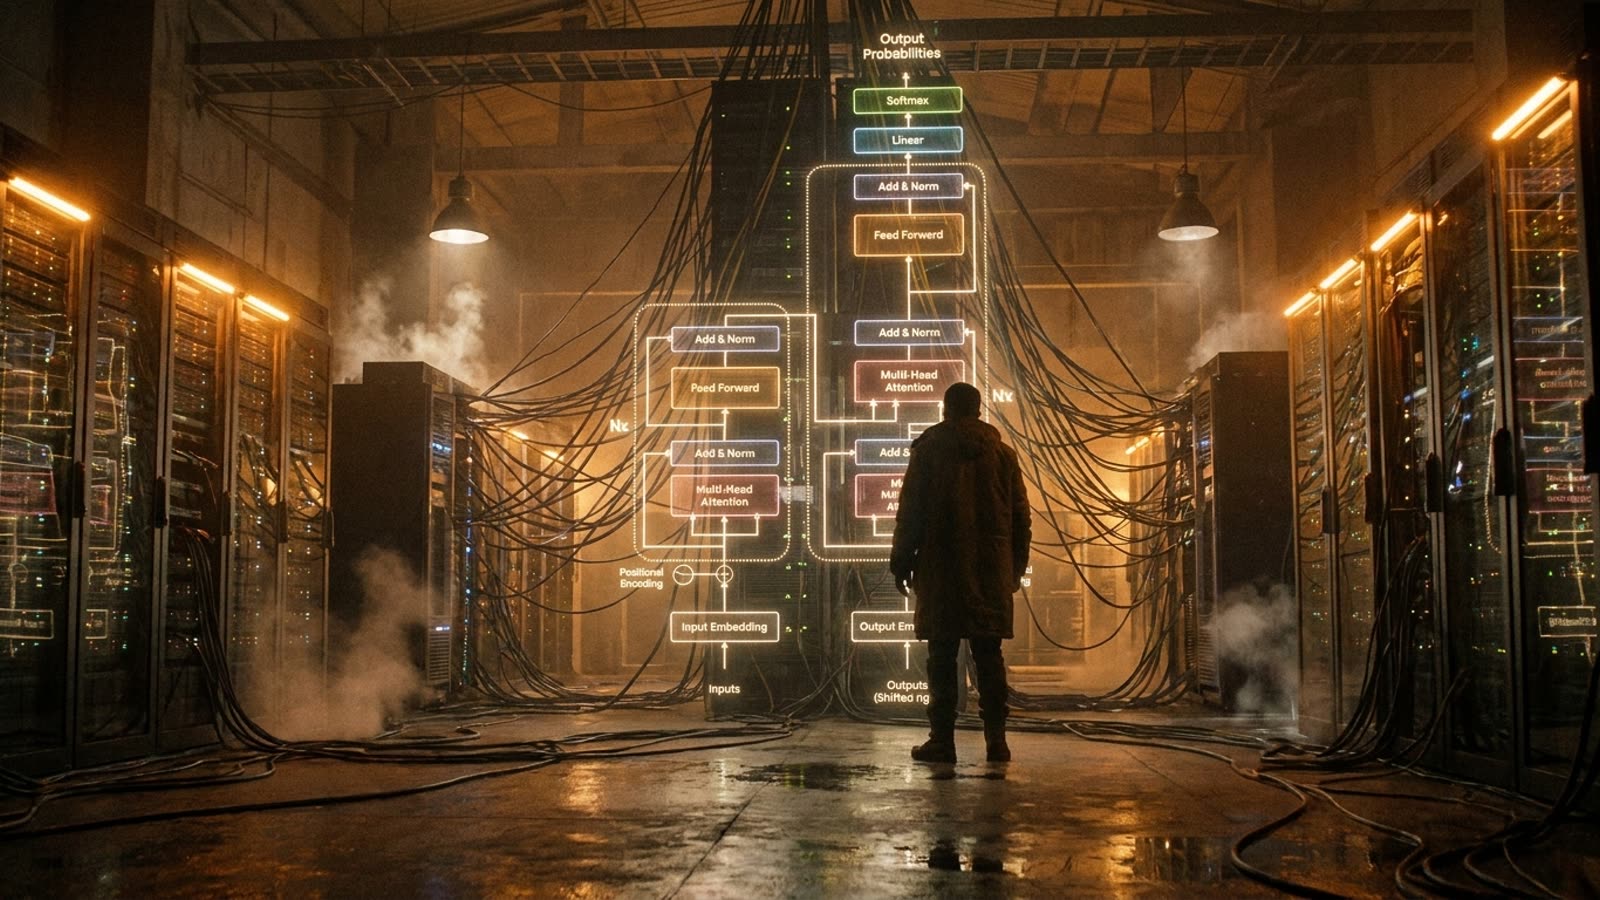
The most consequential technology of the decade runs on a principle your phone has used for years: predicting the next word. When you type "See you" and your keyboard suggests "later" or "tomorrow" or "soon," you are witnessing, in miniature, the same fundamental operation that powers ChatGPT, Claude, and every other large language model reshaping white-collar work. The difference is scale, context, and a mathematical trick called attention.
This is not a metaphor. It is literally what these systems do. A large language model receives a sequence of tokens—fragments of words, punctuation, spaces—and calculates a probability distribution over what token should come next. Then it picks one, appends it to the sequence, and repeats. The apparent intelligence, the uncanny fluency, the moments of genuine insight all emerge from this single operation performed billions of times with extraordinary statistical sophistication.
The attention mechanism explained
Before transformers, language models processed text sequentially, like reading a sentence one word at a time while gradually forgetting the beginning. The transformer architecture, introduced by Google researchers in 2017, solved this with "self-attention"—a mechanism that allows every word to look at every other word simultaneously and decide which relationships matter most.
Imagine reading the sentence: "The animal didn't cross the street because it was too tired." What does "it" refer to? You know instantly it means the animal, not the street, because streets don't get tired. A transformer learns to make this connection by calculating attention scores—numerical weights that determine how much each word should influence the interpretation of every other word. Through training on vast text corpora, the model learns that "tired" strongly connects "it" back to "animal."
This happens across dozens of "attention heads" running in parallel, each potentially capturing different types of relationships: grammatical dependencies, semantic associations, coreference chains. Stack these attention layers deep—modern models have dozens to over a hundred—and the system develops increasingly abstract representations of meaning.
What training actually teaches
The billions of parameters in a large language model are simply numbers—weights that determine how strongly different neurons connect. During training, the model sees enormous quantities of text with random words masked out and must predict what belongs in the gaps. When it guesses wrong, the error propagates backward through the network, nudging millions of weights slightly in directions that would have made the correct prediction more likely.
Repeat this process across trillions of words and something remarkable happens: the model develops internal representations that capture grammar, facts, reasoning patterns, style, and tone—not because anyone programmed these concepts in, but because they help predict text more accurately. A model that understands subject-verb agreement makes better predictions. A model that grasps cause and effect makes better predictions. A model that recognizes when a human would say "I don't know" makes better predictions.
This is why large language models know things nobody explicitly taught them and why they fail in ways that seem bizarre. They are not reasoning from first principles; they are pattern-matching against statistical regularities in human text at a scale that produces emergent capabilities no one fully anticipated.
Why this matters for using AI well
Once you understand that these systems are fundamentally prediction engines, their failure modes become predictable. They struggle with novel reasoning because they are interpolating from training data, not deriving truths. They hallucinate confidently because the training objective rewards fluent, plausible-sounding text, not accuracy. They can be manipulated by prompts that invoke patterns from their training distribution.
But this understanding also reveals their genuine strengths. They excel at tasks that humans have done repeatedly in text: summarization, translation, code completion, stylistic transformation. They are extraordinary at recognizing patterns across contexts too vast for any human to hold in memory. They can serve as thinking partners precisely because they have absorbed more written human reasoning than any person could read in a thousand lifetimes.
Our take
The transformer is neither the harbinger of superintelligence nor a parlor trick. It is a genuinely novel tool—perhaps the most powerful pattern-recognition system ever built—that happens to operate on the medium through which humans externalize thought. Treating it as either a god or a fraud misses what makes it useful: a machine that has learned, through sheer statistical exposure, to simulate the surface structure of human reasoning well enough to be genuinely helpful, while remaining fundamentally incapable of the grounded understanding that even a child possesses. The people who will use AI most effectively are those who internalize this distinction.