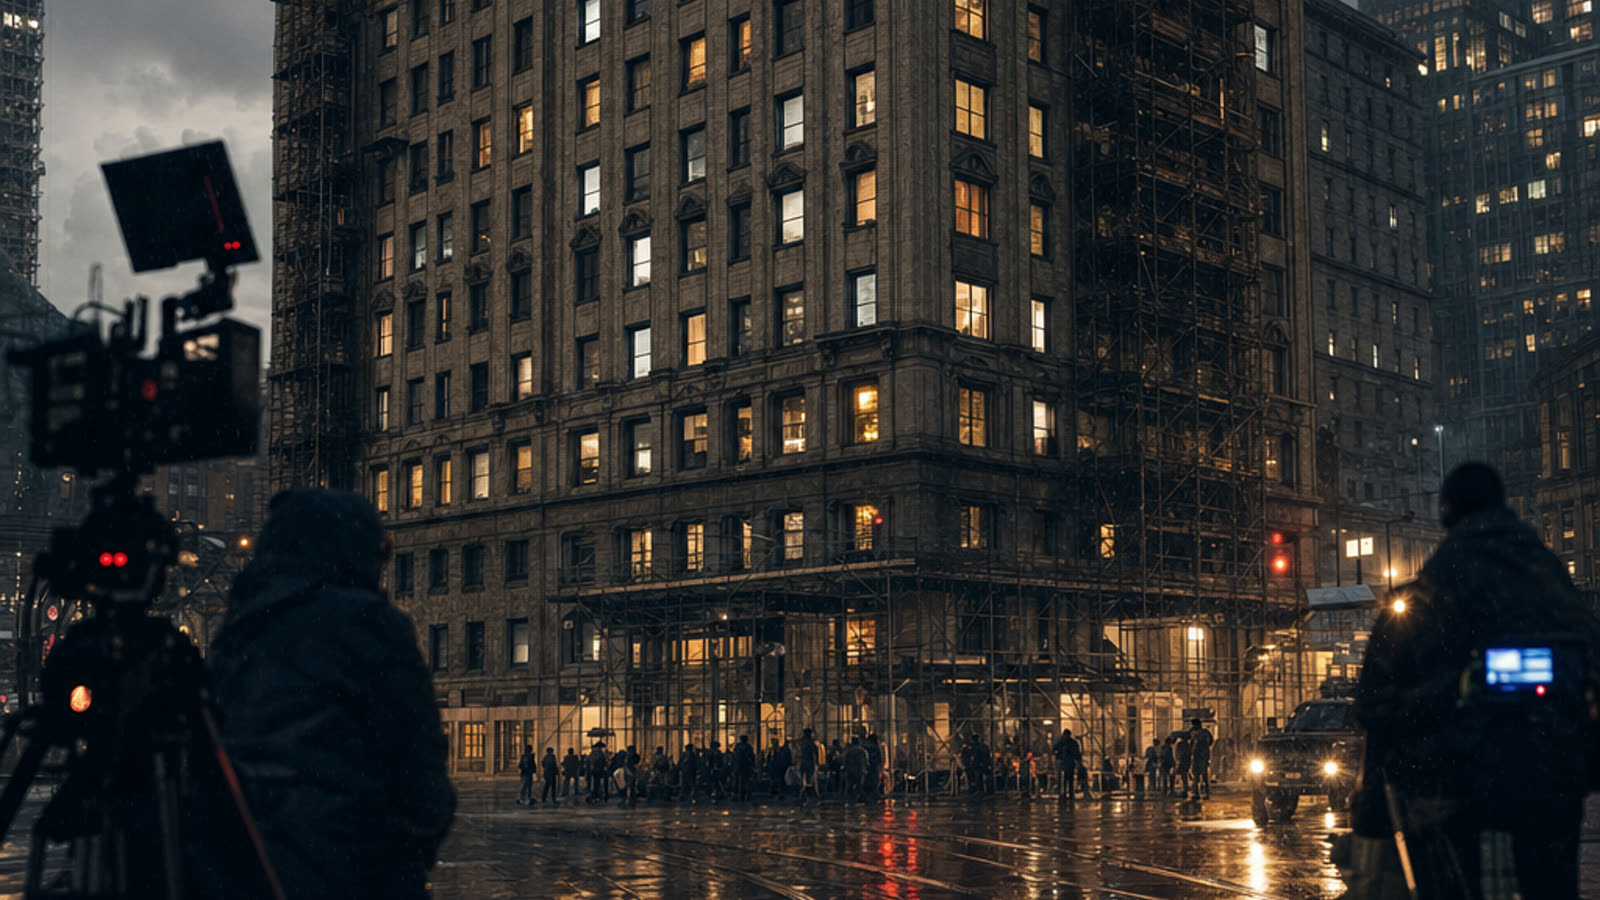
Ask a modern AI system to describe a photograph of a city block and it will wax eloquent about architectural styles, weather conditions, and the mood of pedestrians. Ask it how many windows are on the third floor and it will confidently give you a number that is almost certainly wrong. This is not a bug awaiting a patch. It is a window into how these systems fundamentally differ from human perception.
The phenomenon is so consistent it borders on comedic. Upload an image of a dozen eggs and the model might count eleven, or thirteen, or simply announce "approximately twelve" with the confidence of a sommelier describing terroir. Hand it a chessboard mid-game and request a piece count; prepare for creative arithmetic. The same system that can identify a Monet from a Manet, that can read handwritten text in photographs, that can generate plausible captions in dozens of languages, stumbles on the task a four-year-old masters with pointed fingers.
The architecture of impression
Vision-language models do not see the way humans see. They process images through convolutional or transformer-based encoders that compress visual information into dense numerical representations—embeddings that capture relationships, textures, and semantic content but discard the discrete, countable nature of objects. When you look at a photograph, your visual system can individuate objects, track them, and enumerate them through a process cognitive scientists call subitizing for small quantities and explicit counting for larger ones. The AI has no such mechanism. It perceives the image as a continuous field of features, not a collection of distinct things.
This is why the same model can tell you a crowd looks "large" or "sparse" with reasonable accuracy but cannot reliably tell you whether it contains forty-seven or fifty-three people. It has learned statistical associations between visual patterns and numerical language, not the algorithmic process of counting itself. The number it produces is essentially a sophisticated guess based on pattern matching, not enumeration.
Why this matters beyond party tricks
The counting problem is a proxy for a deeper limitation: these systems struggle with any task requiring precise spatial reasoning about discrete objects. Inventory management, quality control on assembly lines, medical imaging where the number of lesions matters, satellite analysis of vehicle fleets—all domains where fluent description is insufficient and exact quantification is the point. Companies deploying vision AI in these contexts have learned to treat the models as first-pass filters, not final arbiters, with human review or specialized counting algorithms handling the enumeration.
The limitation also illuminates why multimodal AI remains brittle in ways that surprise users accustomed to its linguistic fluency. A system that writes poetry about a photograph cannot reliably answer the most basic factual questions about that photograph's contents. The eloquence is real but shallow in a specific, technical sense: it operates on compressed representations optimized for semantic similarity, not geometric or arithmetic fidelity.
Our take
The window-counting problem is useful precisely because it is so mundane. It punctures the mystique surrounding these systems without diminishing their genuine capabilities. Vision-language models are extraordinary pattern matchers and association engines; they are not general-purpose perceivers. Understanding this distinction is the beginning of using them wisely—and of building the next generation that might, eventually, count to twelve without breaking a sweat.